Duplicate Without User-Selected Canonical: Find the Twin Google Chose
 By Ashikur Rahman17 min read
Quick answer: "Duplicate without user-selected canonical" is not an error. Google found two copies of a page, you did not say which you prefer, and it picked one and dropped the other from Search. Google also says a canonical preference is optional and your site "will likely do just fine" without one. The reason to open the report anyway is the column most people skip: the URL Google chose. When that twin is the right page, leave it alone. When it is a redirect, a parameter copy or a page that serves nothing, you have the failure that hid 36 of 67 pages on a site I own. Everything here was read from Google's documentation on 19 September 2026.
What the status means, in Google's words
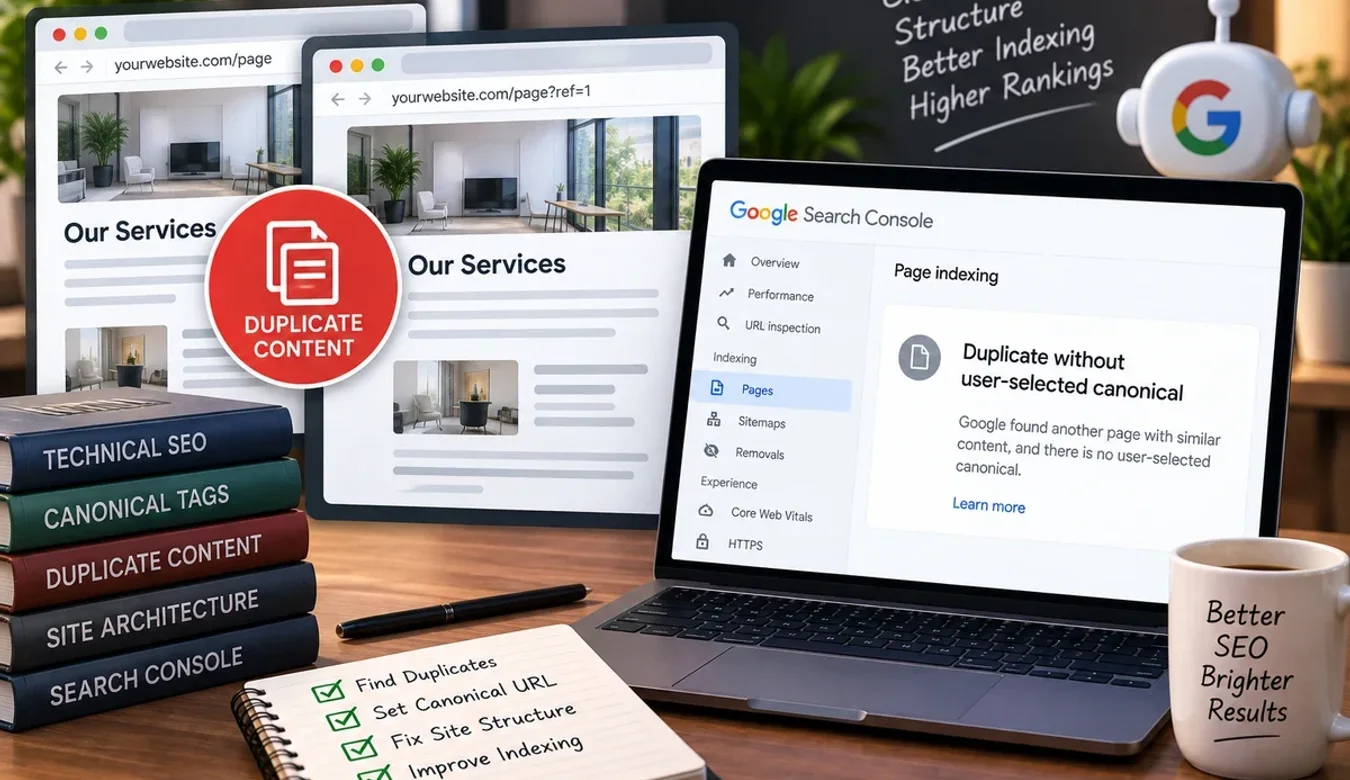
The Page indexing report groups every URL Google knows about under a reason, and the canonical family has four reasons that look alike. Google's help page defines this one as: "This page is a duplicate of another page, although it doesn't indicate a preferred canonical page. Google has chosen the other page as the canonical for this page, and so will not serve this page in Search." The URL in your report is the loser; the winner is shown elsewhere in the same tool. The status describes a decision already made. Here are the four, each in Google's wording.
| Status in the report | Google's definition | What it tells you |
|---|---|---|
| Duplicate without user-selected canonical | "This page is a duplicate of another page, although it doesn't indicate a preferred canonical page. Google has chosen the other page as the canonical for this page, and so will not serve this page in Search." | You declared nothing. Google picked a twin. Check which twin. |
| Duplicate, Google chose different canonical than user | "This page is marked as canonical for a set of pages, but Google thinks another URL makes a better canonical. Google has indexed the page that we consider canonical rather than this one." | You declared a preference and Google overruled it. Your signals disagree with each other. |
| Alternate page with proper canonical tag | "This page is marked as an alternate of another page ... This page correctly points to the canonical page, which is indexed, so there is nothing you need to do." | Working as designed. Ignore. |
| Page with redirect | "This is a non-canonical URL that redirects to another page. As such, this URL will not be indexed. The target URL of the redirect might or might not be indexed, depending on what Google thinks about that target URL." | Expected for any redirected URL. Only a problem if the target is not indexed. |
The first two rows are the pair people confuse. In the first you said nothing. In the second you said something and Google disagreed. The second is covered near the end, because it usually appears after someone fixes the first one badly.
Why Google says you do not have to fix it
Google's canonicalization guide is unusually direct. On whether you need to specify a canonical at all: "none of them are required; your site will likely do just fine without specifying a canonical preference." And on what happens when you do not: "Google will identify which version of the URL is objectively the best version to show to users in Search."
So the status is Google doing the job it said it would do. For most rows in most reports the judgement is correct. The same guide makes one recommendation that clears most of these rows over time: "Do include a rel="canonical" link on the canonical page itself (also known as a self-referential canonical)." The twins usually inherit that tag, and the report then moves them to "Alternate page with proper canonical tag", the row Google says needs nothing.
The reason to care anyway is that the report is the only place Google tells you which twin it trusts, and that answer is sometimes wrong in a way that costs you pages. You cannot know which until you look at the winner.
How to see which twin Google chose
Open the Page indexing report, click the reason, and you get the losing URLs. Pick one and run it through URL Inspection. The indexing section shows two lines: the user-declared canonical, blank for these URLs, and the Google-selected canonical, which is the winner.
Do this for one URL per pattern, not for every URL. A report with 400 rows usually has five or six patterns behind it, and one fix covers each; export the list and sort by URL and they show themselves. Then ask one question of each winner: is this the page you would want a searcher to land on? If yes, the row is harmless. If not, keep reading.
Where the twins come from
Duplicates are almost never written by a person. The platform generates them, and naming the generator is most of the diagnosis, because the fix belongs to the generator, not to the individual URL.
| Generator | Typical pair | Common on | Usual fix |
|---|---|---|---|
| Trailing slash | /guide and /guide/ | Every framework, most hosts | Pick one form, redirect or canonicalise the other |
| Query parameters | /guide/ and /guide/?utm_source=x | Everything with analytics or a cache buster | Self-referential canonical on the clean URL |
| Comment reply links | /post/ and /post/?replytocom=12 | WordPress | Canonical on the post, or disable the parameter |
| Feed copies | /post/ and /post/feed/ | WordPress | Noindex or remove per-post feeds |
| Attachment pages | /image-name/ carrying only the image | WordPress | Redirect attachment pages to the parent post |
| Thin archives | A tag archive holding one post | WordPress | Noindex tags, or stop creating them |
| Print and AMP copies | /post/ and /post/amp/ | Older WordPress, news themes | Canonical from the copy to the original |
| Protocol and host | http, https, www and apex all answering 200 | Misconfigured hosting | Redirect three of the four to the one you want |
| Case | /Guide/ and /guide/ | Case-insensitive servers | Redirect to lowercase |
| Pagination | /category/ and /category/page/2/ | Any archive | Decide whether page 2 exists; if not, redirect it |
| Faceted filters | /shoes/ and /shoes/?size=9&colour=red | Directories, stores, frameworks with search params | Canonical to the unfiltered page; strip default params |
| Staging copies | site.com/page/ and staging.site.com/page/ | Anyone who forgot | Password the staging host |
Two rows deserve a note. Faceted filters can turn one hub into hundreds of URLs, and the frameworks that generate them sometimes redirect between the copies too, which is the harmful case below. Protocol and host duplicates are the only case with a stated Google default: the guide says Google "prefers HTTPS pages over equivalent HTTP pages as canonical", and states no default for trailing slashes or www, so those are yours to settle. On WordPress the plugin that manages your titles usually writes your canonical tags too; what that costs in page weight is covered in whether Yoast slows down WordPress.
The three signals Google actually ranks
Most advice ends with "add a canonical tag". That is one of three tools, and Google ranks them in order of strength. Redirects are "A strong signal that the target of the redirect should become canonical." A rel="canonical" annotation is "A strong signal that the specified URL should become canonical." Sitemap inclusion is "A weak signal that helps the URLs that are included in a sitemap become canonical."
Read that last one again, because it kills a common fix. Removing losers from the sitemap, or adding winners, is a weak signal by Google's own description. If the sitemap already lists the clean URL and Google still picked the parameter copy, the sitemap was never going to win that argument.
So the practical order is the reverse of how people usually try things. Decide whether the twin should exist at all. If not, redirect it. If it should exist for users but not as a separate result, put a canonical tag on it pointing at the page you want, and a self-referential tag on that page. Only then tidy the sitemap. Note also what the guide says by omission: both strong signals are signals, not instructions. When they contradict each other, or contradict what Google sees on the page, you get the second status in the table rather than the first.
Work with me
Not sure which twin to keep? I will read the export for you.
The Page indexing export answers this in an afternoon if you know how to group it. Every duplicate row has a generator behind it: a parameter, a slash, a feed, a filter, a staging copy. Once the rows are grouped by generator, the fix for each group is usually one line, and the rows that actually matter are the handful where Google's chosen canonical is a redirect or a page that serves nothing.
Send me the Search Console export and the domain. I will group the duplicates, name the generator behind each group, and tell you which URLs to canonicalise, which to redirect and which to leave exactly as they are. On my own directory a canonical pointing at a zero-byte redirect had quietly hidden 36 of 67 pages, so I look for that first. If your report is the harmless kind, I will say so and you will have lost nothing.
Ashikur Rahman
SEO and AI Search Specialist
The contact links above go to me directly, so I earn from it if you hire me. Nothing else on this page is a paid placement.
A harmless twin: the no-slash copies on this site
Here is the harmless kind, on a site whose report I can read in full. On 19 September 2026 this site moved from WordPress onto a server-rendered framework hosted on Lovable, configured to always use trailing slashes. The host answers the no-slash form with a 200 as well, serving the same prerendered page rather than redirecting. Every one of the site's 101 URLs has a twin.
What makes it harmless is that the no-slash copy carries the same self-referential canonical as the slash copy, pointing at the slash URL. Google's strong signal is on both twins and agrees with the sitemap. In the live crawler audit run the day of the move, the pairs resolved without a redirect and without a broken link across all 101 pages.
Two other twins from the same migration were handled the other way: the old category pagination URLs now 301 to the single category URL, and the default WordPress archive's paginated URLs redirect to the homepage. Those twins should not exist, so they got the strongest signal. The www form is a third case: the host redirects it to the bare domain with a 302, which the project cannot change. A redirect is a strong signal whatever its code, but it shows a twin generator sitting above the layer your CMS settings can reach.
If you build on the same stack, the configuration decisions that produced this result, including why the sitemap has to be a server route, are written up in the Lovable SEO settings checklist.
A harmful twin: when the chosen canonical is a redirect
Now the other kind, on another site I own: a directory on the same framework family that lost almost all of its indexing in August 2026. The full investigation is already on this site, in why a vibe-coded site stops ranking and the Discovered, currently not indexed write-up, so here is only the canonical part.
The registry page was the one hub that linked to all 36 profile pages. Its search filters each had a default value. Because of those defaults, the framework normalised the clean registry URL into a fully parameterised URL by way of a 307 redirect, and that redirect served zero bytes. The parameterised URL, the only one that rendered anything, then declared its canonical to be the clean URL. The clean URL was the redirect.
Follow the loop from Google's side. It requests the clean hub, receives an empty redirect, follows it to the parameter copy, and the copy says: the real page is the URL you just came from. A strong signal tells Google that the canonical version of the site's only hub serves nothing. The 36 profiles behind it had no other crawlable path.
The report status was not this one, because a canonical had been declared, but the mechanism is exactly what you check for in the Google-selected canonical column: the chosen twin was a redirect. The fix was one line, stripping the default search parameters so the bare URL resolves directly. Verified on 17 September 2026, the registry URL returns 200 with a self-referential canonical and all 36 links present. This is why "ignore the status" is right in general and wrong in particular. Ignore it when the winner is the right page. Do not ignore it when the winner redirects, serves an empty body, carries parameters, or lives on a host you never meant to publish from.
Keep, redirect or remove
Once the twins are grouped by generator and each group's winner is checked, every row falls into one of three decisions. This is the table I work from.
| Situation | Decision | Signal to send | Then |
|---|---|---|---|
| Winner is the right page, loser is a parameter or slash copy | Keep both, canonicalise | Self-referential rel="canonical" on the winner; the copy inherits it | Expect the row to move to "Alternate page with proper canonical tag" |
| Loser has no reason to exist (old pagination, attachment page, feed copy) | Redirect | 301 to the winner | Drop the loser from the sitemap; get the old URL recrawled |
| Loser is real content that overlaps a stronger page | Merge, then redirect | Move anything unique into the winner, then 301 | Repoint internal links to the winner |
| Loser is junk that should never have been generated (staging, case variants) | Remove | 410, or password the host | Fix the generator so it stops |
| Winner is a redirect, an empty response or a parameter copy | Fix the winner first | Make the clean URL serve the page directly, with a self-referential canonical | Re-inspect before touching the losers |
| Winner is on a host or protocol you did not intend | Redirect at the server | 301 from the wrong host or protocol to the right one | Check that the right host also declares itself canonical |
The last two rows justify reading the report at all. Everything above them is housekeeping Google would mostly get right on its own; the bottom two are where Google got it right by its own logic and wrong by yours, because the strongest signal on the page pointed somewhere you never meant it to.
Redirecting the losers without losing them
When the decision is redirect, there is a step afterwards that nearly everyone misses, and I missed it once. In July 2026 I consolidated a third site I own from 56 posts to 18: 40 URLs were redirected with 301s in both slash forms, and the sitemap went from 69 URLs to 31. The site pinged IndexNow after every deploy, building its URL list from the sitemap, so it submitted the 31 survivors, the one set of URLs that needed no attention. The 40 redirected URLs, the ones engines had to revisit to discover the redirects at all, were never submitted, because they were no longer in the sitemap. I submitted them by hand.
A redirect only works once a crawler fetches the old URL and sees it. If your recrawl requests come from a sitemap that now lists only winners, the losers are revisited on Google's schedule, not yours. Inspect a sample of the old URLs, submit them directly where an engine allows it, keep the redirects indefinitely, and repoint your own links at the same time so no navigation still teaches crawlers that the old URL is part of the site.
What validation does, and what it cannot do
The Validate fix button asks Google to re-check the URLs under a reason. Google's help page says "Validation typically takes up to about two weeks, but in some cases can take much longer, so please be patient." It does not speed up indexing or change a canonical choice. Validate a group only after changing its signals, and expect rows to move rather than disappear: a slash copy that inherits a canonical reappears under "Alternate page with proper canonical tag", a redirected loser under "Page with redirect". Both are correct outcomes that still count as exclusions.
If the rows instead reappear under "Duplicate, Google chose different canonical than user", you created the second status by fixing the first: you declared a canonical and Google disagreed, usually because the tag points at a redirect, disagrees with the sitemap, or points across hosts or protocols. Google calls the tag a strong signal, not a command. Go back to the winner and make every signal agree.
This status belongs to a family of exclusion reasons that are easy to misread as penalties. The pair that causes the most wasted rewrites is explained in what Crawled, currently not indexed means about a page Google already read. The discipline is the same: read Google's definition, find what Google decided, and act on the decision rather than the label.
The short version
"Duplicate without user-selected canonical" means Google found two copies, you declared no preference, and Google picked one. By Google's own account the site "will likely do just fine" without a declaration, so treat the status as information, not a fault. Export the report, group the losers by generator, inspect one winner per group. If the winner is the page a searcher should land on, add a self-referential canonical and stop. If the loser has no reason to exist, redirect it; redirect and canonical tag are Google's two strong signals, the sitemap is a weak one. The rows worth your afternoon are the few where the winner is a redirect, an empty response or a parameter copy, the shape that hid 36 of 67 pages on a site I own. Fix the winner first, make every signal agree, then validate and wait the two weeks.
Frequently asked questions
What does "duplicate without user-selected canonical" mean in Google Search Console?
Google found that a URL is a copy of another page, neither copy carried a canonical tag naming a preferred version, and Google chose the other copy for Search. Its definition ends with the consequence: it "will not serve this page in Search". The listed URL is the copy Google dropped; the copy it kept appears as the Google-selected canonical in URL Inspection.
Do I need to fix duplicate without user-selected canonical?
Usually not. Google's canonicalization guide says a site "will likely do just fine without specifying a canonical preference". The exception is when the copy Google chose is wrong for you: a redirect, a parameterised URL, an empty response or a page on a host you never meant to publish. Check the chosen canonical first and act only on the groups where it is wrong.
How do I find which URL Google chose as canonical?
Run an affected URL through URL Inspection. The indexing section shows the user-declared canonical, blank for this status, and the Google-selected canonical, which is the page Google kept. Check one URL per duplicate pattern rather than every row; URLs made by the same generator share the same kind of winner.
Is a canonical tag or a 301 redirect better for duplicate content?
Google ranks both as strong signals: a redirect is "A strong signal that the target of the redirect should become canonical" and a rel="canonical" annotation "A strong signal that the specified URL should become canonical." Redirect when the duplicate should not exist as a page; use the tag when users still need the copy. Sitemap inclusion is a weak signal and no fix on its own.
Why does my WordPress site have so many duplicate without user-selected canonical URLs?
WordPress generates copies by design: comment reply parameters, per-post feeds, attachment pages, single-post tag archives and pagination, plus tracking parameters from analytics. Most disappear once every post carries a self-referential canonical, because the copies inherit it and move to "Alternate page with proper canonical tag". Attachment pages and one-post archives are better redirected or set to noindex.
Can duplicate without user-selected canonical hurt my rankings?
Not directly. The dropped copy was never going to rank separately, and the kept copy is the one Google judged best. Harm comes only when Google's choice is a URL that does not work, such as a redirect or a page serving an empty body. Then the real page is effectively hidden, and pages linked only from it can drop out of the index with it.
What is the difference between this and "Duplicate, Google chose different canonical than user"?
Here you declared no canonical and Google chose one. There you declared a canonical and Google overruled it. The second usually means your signals disagree: a tag pointing at a redirect, a tag that conflicts with the sitemap, or a tag pointing across hosts. Google treats the tag as a strong signal, not an instruction, and will not follow it into a broken destination.
Should I remove duplicate URLs from my sitemap?
Yes, but not as the fix. The sitemap should list the pages you want indexed, so remove losers and keep winners. Google calls sitemap inclusion "A weak signal", so a cleaner sitemap will not change which twin Google picks. Set the redirect or the canonical tag first, then make the sitemap agree with them.
How long does validation take for this status?
Google's help page says validation "typically takes up to about two weeks, but in some cases can take much longer". It only re-checks the URLs; it does not speed anything up or change Google's choice. Expect fixed rows to move to "Alternate page with proper canonical tag" or "Page with redirect" rather than vanish, since both are correct outcomes that still count as exclusions.
Do trailing slash URLs count as duplicates?
Yes, if both forms return a 200. Google states a default preference for HTTPS over HTTP but none for trailing slashes or for www against the bare domain, so that choice is yours. Redirect one form to the other, or give both the same self-referential canonical pointing at your preferred form. On this site the host serves both forms with a canonical pointing at the slash version, and the pairs resolve without a redirect.
Transparency: every status definition, the three canonicalization signals and the validation timeline in this article were read from Google's Search Console Help page for the Page indexing report and from Google Search Central's canonicalization guide on 19 September 2026. Where Google publishes no rule, such as for trailing slashes, this article says so rather than substituting one. The three case studies are sites I own personally. I sell technical SEO and indexing diagnosis myself, which is a commercial interest you should weigh when reading the recommendation above. There are no affiliate or tracking links on this page.