Should You Block AI Crawlers? Read the Bot List Before You Decide
 By Ashikur Rahman17 min read
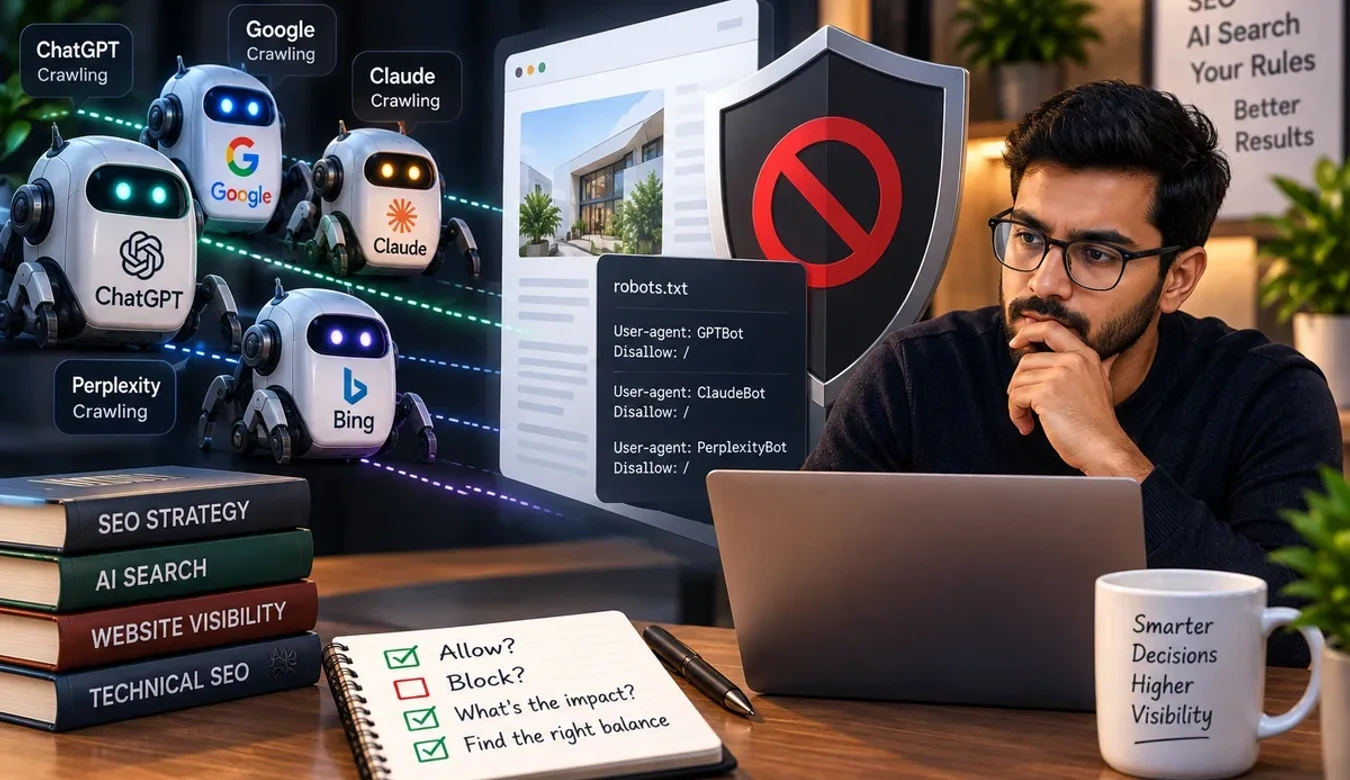
Quick answer: for most sites, no, and the reason is that "AI crawler" is not one thing. The companies publish three separate jobs under three separate names: a training crawler, a search indexer and a fetcher that acts for a user in real time. OpenAI's own page says blocking GPTBot keeps your content out of model training but says nothing about search, while blocking OAI-SearchBot means "Sites that are opted out of OAI-SearchBot will not be shown in ChatGPT search answers." Google's Google-Extended does not touch AI Overviews at all. And the user-triggered fetchers from OpenAI, Perplexity and Meta say in writing that robots.txt may not apply to them. Read the list first. Then block the one job you actually object to, if any.
"AI crawler" is three jobs, and the companies name each one
The block lists that circulate online treat every bot with an AI company's name on it as the same animal. The documentation does not. OpenAI, Anthropic, Google, Apple, Perplexity and Meta each publish a page naming their user agents, and those pages sort into three jobs: training (pages that may end up in a model), search (an index so the assistant can cite and link you) and fetching (opening your page live because a person asked). Each job has its own token. Here is the list as the companies publish it, read on 19 September 2026.
| Token | Company and job | robots.txt | What blocking it costs you |
|---|---|---|---|
| GPTBot | OpenAI, training. Crawls "content that may be used in training our generative AI foundation models". | Respected | Your pages are left out of training. Search is not affected. |
| OAI-SearchBot | OpenAI, search. "used to surface websites in search results in ChatGPT's search features". | Respected | You disappear from ChatGPT search answers. |
| ChatGPT-User | OpenAI, fetch. Used for "certain user actions in ChatGPT and Custom GPTs". | "robots.txt rules may not apply" | Little. It is "not used to determine whether content may appear in Search". |
| ClaudeBot | Anthropic, training. Collects "web content that could potentially contribute to their training". | Respected | Left out of Claude's training data. |
| Claude-SearchBot | Anthropic, search. "navigates the web to improve search result quality for users". | Respected | Weaker presence in Claude's search answers. |
| Claude-User | Anthropic, fetch. "When individuals ask questions to Claude, it may access websites using a Claude-User agent." | Respected | Claude cannot read your page for a user who asks about it. |
| Google-Extended | Google, training only. Controls use "for training future generations of Gemini models". | Respected | Nothing in Search or AI Overviews; it "does not affect a site's inclusion in Google Search". |
| Googlebot | Google, search. The one crawler behind Search, AI Overviews and AI Mode. | Respected | You leave Google. There is no AI-only version of this block. |
| Applebot-Extended | Apple, training. Opt out of "Apple's general purpose foundation models". | Respected | Nothing in search; pages "can still be included in search results". |
| PerplexityBot | Perplexity, search. "not used to crawl content for AI foundation models". | Respected | You leave Perplexity's results. |
| Perplexity-User | Perplexity, fetch. "supports user actions within Perplexity". | "generally ignores robots.txt rules" | Nothing; the block is not honoured. |
| Meta-ExternalAgent | Meta, training and indexing. "training foundation AI models or improving products by indexing content directly". | Respected | Out of Meta's training and product indexes. |
| Meta-ExternalFetcher | Meta, fetch. "fetches individual links at a user's request". | "may bypass robots.txt" | Nothing reliable. |
| CCBot | Common Crawl, open web archive used by many. | Respected | Out of the public crawl and every dataset built from it. |
Two things stand out once the list is laid flat. Training and search are always separate tokens, so you can refuse one and keep the other. And every fetcher for live user requests either says robots.txt may not apply to it or, in Anthropic's case, honours the file but only visits when a person asks. Blocking the fetchers is either ineffective or pointless.
Blocking GPTBot does not remove you from ChatGPT search
This is the mistake that costs sites the most, because it feels like caution and behaves like a penalty. OpenAI's crawler page separates the two bots. Disallowing GPTBot means content "should not be used in training generative AI foundation models". Of OAI-SearchBot it says: "Sites that are opted out of OAI-SearchBot will not be shown in ChatGPT search answers."
So blocking GPTBot alone costs a seat in the training set and nothing else. Copying a block list that includes OAI-SearchBot removes you from the one surface where ChatGPT links out to websites. Most pasted lists include both tokens. Few of the people pasting them wanted the second outcome.
The same shape holds at Anthropic. ClaudeBot trains; Claude-SearchBot "navigates the web to improve search result quality for users". Anthropic's help page says all three of its bots "respect 'do not crawl' signals by honoring industry standard directives in robots.txt" and publishes its source IP ranges at claude.com/crawling/bots.json. To be cited, keep OAI-SearchBot, Claude-SearchBot and PerplexityBot open. To stay out of training, close GPTBot, ClaudeBot, Google-Extended, Applebot-Extended, Meta-ExternalAgent and CCBot. The two lists do not overlap.
Earning the citation once the door is open is covered in how to rank in AI Overviews and how to get cited in ChatGPT. Nothing in either works if the search bots cannot fetch the page.
Google-Extended does not touch AI Overviews
Google's crawler documentation is precise about what Google-Extended is. It controls whether "content Google crawls from their sites may be used for training future generations of Gemini models". It "does not affect a site's inclusion in Google Search nor is it used as a ranking signal in Google Search". That is the whole scope. It is a training switch.
AI Overviews and AI Mode are Search features built from the same Googlebot crawl as the blue links. Google's AI features page says sites appearing in them "are included in the overall search traffic in Search Console", reported under the Web search type. There is no AI-Overview-only opt-out anywhere in Google's documentation; the controls it points to are nosnippet, data-nosnippet, max-snippet and noindex, each of which limits what Google shows from your page everywhere in Search. The page's one pointer elsewhere is: "To limit AI training and grounding in some of Google's other systems, read more about Google-Extended."
So you cannot stay in Google and out of its AI answers. Google-Extended changes Gemini training and nothing else. Blocking Googlebot removes you from Search entirely. Nosnippet or data-nosnippet on a passage keeps it out of every snippet and every AI summary, ordinary search snippets included. That is the full menu, and anyone selling a fourth option is selling something Google does not offer.
The fetchers say, in writing, that the file may not apply
The third job is where block lists become theatre. OpenAI's page on ChatGPT-User says "robots.txt rules may not apply", and that the agent is "not used to determine whether content may appear in Search". Perplexity's page says of Perplexity-User: "Since a user requested the fetch, this fetcher generally ignores robots.txt rules." Meta's page says Meta-ExternalFetcher "may bypass robots.txt" because it performs fetches a user asked for, and that even FacebookExternalHit, the link-preview bot, "might bypass robots.txt when performing security or integrity checks".
Their logic is that a human asked to see the page, so the request is closer to a browser visit than a crawl. You can disagree, but a disallow line will not change it. To stop these agents you need the server, the CDN or the firewall, where a request can be refused rather than asked to leave. Robots.txt is the wrong tool for the one category of bot people most want to stop.
Work with me
Not sure which bots your site is actually letting in?
The robots file is the smallest part of this. On the sites I audit, the answer to who gets served lives in three other places: the firewall rules, the CDN's bot settings and the raw server logs. A site can allow every AI crawler in robots.txt and still return nothing to them, and the owner finds out months later when the citations never arrive. I read all four together and write down, bot by bot, who is allowed, who is blocked and who is being dropped by accident.
Send me the domain and tell me what you want from AI search: citations, training opt-out, or both. I will come back with the current state of access for the crawlers that matter, the changes needed in plain terms, and a robots file you can paste. If everything is already open and working, I will say so, and the check costs you nothing.
Ashikur Rahman
SEO and AI Search Specialist
The contact links above go to me directly, so I earn from it if you hire me. Nothing else on this page is a paid placement.
What robots.txt can and cannot do, in Google's words
Google's introduction to robots.txt says it "is not a mechanism for keeping a web page out of Google", that "A page that's disallowed in robots.txt can still be indexed if linked to from other sites", and on enforcement: "While Googlebot and other respectable web crawlers obey the instructions in a robots.txt file, other crawlers might not."
So the file is a request. Well-run crawlers honour it, badly run ones do not, and nothing in the file can make them. That is why each company's page is worth reading: it tells you whether that bot will comply.
There is one rule about how the file is read that trips up almost every AI block list. Google's page on writing the file states: "A user agent can match only one rule set, which is the first, most specific group that matches a given user agent." A bot that finds its own name follows that group and ignores everything else, including the catch-all. So a named GPTBot group with Allow: / is not touched by a later Disallow under User-agent: *, and a named GPTBot group with a single Disallow: /private/ allows GPTBot everywhere else, whatever the catch-all says. Named groups are complete policies, not additions.
The file has to sit at the root of the host it governs, and a Sitemap line must carry a fully qualified URL, because Google "doesn't assume or check http/https/www.non-www alternates".
Cloudflare's default block, and what its numbers actually claim
On 1 July 2025 Cloudflare changed the default for new domains on its network to block AI crawlers "unless they pay creators for their content", and introduced a scheme it calls Pay per Crawl. Cloudflare framed the change with a comparison of how much crawling now happens per referral visit sent back. In its words, against "the Google of old", getting traffic is "750 times more difficult" via OpenAI and "30,000 times more difficult" via Anthropic. Those are Cloudflare's figures and Cloudflare's framing, published by a company selling the block.
Two things are true at once about that argument. The imbalance is real: an answer engine reads far more than it links. And the framing counts every crawl as a cost and every referral as the only benefit, which is the accounting of a publisher paid per pageview. A service business or a review site earns from being named in the answer whether or not the reader clicks, so for that kind of site the crawl is the point. The default block also lumps the training and search jobs together, and the table above shows they are different bots with different consequences.
If your site was added to Cloudflare after that date, assume AI crawlers are blocked until you check the AI Crawl Control settings. The edge refuses the request before your server sees it, so the setting overrides whatever robots.txt says.
Which sites should block, by type
The answer depends on how the site earns and what it wants from the assistants.
| Site type | Training bots | Search bots | Reasoning |
|---|---|---|---|
| Publisher paid per pageview or by subscription | Block | Decide by test | Training returns nothing. Search bots may send readers or may replace the visit; measure referrals for a quarter before deciding. |
| Service business, practice, agency, consultancy | Allow | Allow | The value is being named as the answer. A blocked search bot removes you from the recommendation; a blocked training bot removes you from what the model knows by default. |
| Review or affiliate site | Allow | Allow | Citations carry the brand and the comparison. The one thing an affiliate cannot survive is invisibility in the surface where buyers now ask. |
| SaaS documentation and help centre | Allow | Allow | An assistant that can read the docs answers your customers' questions correctly. A blocked one guesses. |
| Original research, datasets, paid reports | Block | Allow | Keep the search citation for the summary page; withhold the body from training. Use data-nosnippet on the passages you sell. |
| Personal blog or portfolio | Your choice | Allow | Training is a values question with no revenue attached. Search costs nothing to allow. |
CriticNest is the second and third rows at once: one person selling SEO and AI search work and reviewing the tools he uses, so every AI impression is a chance for the name to appear in the answer. The site's own Search Console Generative AI report, written up in what the Generative AI report actually shows, recorded 33,600 AI impressions in its window, and one page was picked up eleven days after publishing. Blocking the bots that produced that would be an odd way to run a site that exists to be found. And before paying for any of the trackers compared in what AI visibility tools cost, confirm the bots can reach you at all; a dashboard cannot measure a surface you have been excluded from.
How to write the file so it says what you mean
Given the one-group rule, the safest structure names every bot you have a view on, gives each a complete group, and ends with a catch-all, so a later edit to the catch-all can never quietly change a named bot's access. This is the shape CriticNest shipped on 19 September 2026: 63 named User-agent groups, each with Allow: /, then a catch-all, then the sitemap. Nothing is disallowed; the named groups are explicit opt-ins.
A site that wants to stay out of training but remain in search would write the same structure with the training tokens flipped:
User-agent: GPTBot
Disallow: /

User-agent: ClaudeBot
Disallow: /

User-agent: Google-Extended
Disallow: /

User-agent: Applebot-Extended
Disallow: /

User-agent: Meta-ExternalAgent
Disallow: /

User-agent: CCBot
Disallow: /

User-agent: OAI-SearchBot
Allow: /

User-agent: Claude-SearchBot
Allow: /

User-agent: PerplexityBot
Allow: /

User-agent: *
Allow: /

Sitemap: https://www.example.com/sitemap.xml
Three notes. Googlebot is not named, so it falls through to the catch-all and stays allowed. Google-Extended is a training switch only, so its Disallow leaves Search and AI Overviews untouched. And ChatGPT-User, Perplexity-User and Meta-ExternalFetcher are left out on purpose: their own documentation says a line here may not bind them, and a rule a bot has told you it will not read is a false record of what your site permits. Bing is absent for a different reason: Microsoft controls generative use with per-page NOCACHE and NOARCHIVE meta tags, not a crawler token, so no robots.txt line covers it.
On a Lovable-hosted or TanStack Start site the file is a static asset served from the public folder, and the rest of the indexing set-up around it, including the sitemap route and per-page metadata, is covered in the Lovable SEO settings checklist.
The firewall decides, not the text file
Everything above assumes the crawler reaches your server and reads the file. On many sites it does not. Firewalls, CDN bot-management rules and hosting-level protections classify requests before robots.txt is fetched, and their default lists often include AI user agents.
A client site I audited this year, an orthodontic practice, had a robots.txt that allowed everything. Its firewall was silently dropping five AI crawlers. The owner believed the site was open; the logs showed the requests arriving and being refused. Nothing in the text file was wrong. The firewall, not the file, decided.
The reverse case exists too. Lovable-hosted sites on the older React and Vite stack serve pre-rendered HTML only to crawlers the platform has verified; an unverified agent sees an empty shell whatever robots.txt says. Access is decided in layers, and the file is the outermost and weakest of them.
So the check is four checks read together: the file, the CDN's bot settings, the firewall's user-agent and IP rules, and the raw access log filtered by the tokens above. A bot logged with 200 responses and full byte counts is being served. One logged with 403s, or 200s and near-zero bytes, is being refused between itself and your content. One that never appears has either not found you or is being dropped before it logs. Only the log tells you which.
Once the bots are in, the other half is measurement. Google now assigns assistant referrals to their own Analytics channel, and reading that against the Search Console impression data is covered in how to track AI traffic in GA4.
The short version
Stop asking whether to block "AI crawlers" and ask which of the three jobs you object to. Training crawlers (GPTBot, ClaudeBot, Google-Extended, Applebot-Extended, Meta-ExternalAgent, CCBot) can be refused without touching any search product. Search indexers (OAI-SearchBot, Claude-SearchBot, PerplexityBot, and Googlebot itself) put your name in answers; block them only once you have measured that the visit matters more than the mention. User-triggered fetchers say the file may not apply, so a rule for them records intent and nothing more. Google offers no AI-Overview-only opt-out. Write named groups as complete policies. Then read your firewall and your logs, because where this goes wrong, the text file was never the thing deciding.
Frequently asked questions
Should I block AI crawlers on my website?
Only the ones doing a job you object to. Training crawlers such as GPTBot, ClaudeBot and Google-Extended can be blocked without affecting search visibility. Search indexers such as OAI-SearchBot, Claude-SearchBot and PerplexityBot are what get you cited; blocking them removes you from those answers. A service business, review site or documentation site should allow both. A publisher paid per pageview should block training and measure search referrals before deciding the rest.
Do AI crawlers respect robots.txt?
The training and search crawlers from OpenAI, Anthropic, Google, Apple, Perplexity and Meta all say they honour it. The user-triggered fetchers differ: OpenAI says of ChatGPT-User that "robots.txt rules may not apply", Perplexity says Perplexity-User "generally ignores robots.txt rules", and Meta says Meta-ExternalFetcher "may bypass robots.txt". Google adds that the file cannot enforce anything and "other crawlers might not" obey it.
Does blocking GPTBot stop my site appearing in ChatGPT?
No. GPTBot is OpenAI's training crawler. The search crawler is OAI-SearchBot, and OpenAI states that sites opted out of OAI-SearchBot "will not be shown in ChatGPT search answers". Blocking GPTBot alone leaves ChatGPT search untouched. Most copied block lists include both tokens, which is how sites drop out of ChatGPT search without meaning to.
Does Google-Extended block AI Overviews?
No. Google's documentation says Google-Extended controls whether content is used "for training future generations of Gemini models" and that it "does not affect a site's inclusion in Google Search nor is it used as a ranking signal". AI Overviews and AI Mode are Search features built from Googlebot's crawl. Google publishes no AI-Overview-only opt-out; the available controls are nosnippet, data-nosnippet, max-snippet and noindex, which also affect ordinary snippets.
How do I block AI crawlers in robots.txt?
Add a named group per bot, for example User-agent: GPTBot followed by Disallow: /, and keep a catch-all User-agent: * group for everyone else. Google's rule is that a bot follows only "the first, most specific group that matches", so a named group is a complete policy for that bot and nothing in the catch-all applies to it. Put the file at the host root and include a fully qualified Sitemap URL.
Which AI bots ignore robots.txt?
The ones acting on a live user request. ChatGPT-User (OpenAI), Perplexity-User (Perplexity) and Meta-ExternalFetcher (Meta) each say on the company's own page that robots.txt may not apply, because a person asked for the page. FacebookExternalHit may also bypass it for security checks. Anthropic's Claude-User says it does honour the file. To stop a fetcher that ignores the file you need a server, CDN or firewall rule, not a text line.
Does Cloudflare block AI crawlers by default?
For new domains added to Cloudflare since 1 July 2025, yes. Cloudflare changed the default to block AI crawlers "unless they pay creators for their content" and launched a Pay per Crawl scheme. The block is applied at the edge and overrides an allow in your robots.txt, so check the AI Crawl Control settings before assuming your file is being read.
Will blocking AI crawlers hurt my Google rankings?
Blocking GPTBot, ClaudeBot, Google-Extended or Applebot-Extended has no effect on Google Search; Google says Google-Extended is not a ranking signal. Blocking Googlebot itself removes you from Search, AI Overviews included. The real risk in block lists is that some include OAI-SearchBot or PerplexityBot, which removes you from those engines' answers.
How can I tell whether AI crawlers can actually reach my site?
Read the access log filtered by the bot tokens. A crawler logged with 200 responses and full byte counts is being served. One logged with 403s, or 200s with near-zero bytes, is being refused by a firewall or CDN rule. One that never appears is either not visiting or being dropped before it logs. An allow line in robots.txt tells you nothing about which of the three is happening.
Can I stay in Bing search but out of Microsoft's AI answers?
Partly, and with meta tags rather than robots.txt. Bing's webmaster blog describes NOCACHE, under which Bing will "only display URL/Snippet/Title in the answer", and NOARCHIVE, under which content "will not be included in Bing Chat answers" and is not used for training. Both are set per page with a bingbot meta tag. There is no separate Bing training crawler to block in robots.txt.
Transparency: every user-agent token, purpose and robots.txt statement in this article was read from the publishing company's own documentation on 19 September 2026: OpenAI's crawler overview, Anthropic's help centre, Google's crawler and robots.txt documentation, Apple's Applebot page, Perplexity's crawler guide, Meta's web crawler reference, Common Crawl's CCBot page and Microsoft's Bing webmaster blog. Cloudflare's figures are Cloudflare's own framing from its 1 July 2025 announcement. Where a company publishes nothing on a point, this article says so rather than substituting a guess. I sell AI search and access audits myself, which is a commercial interest you should weigh. There are no affiliate or tracking links on this page.